Publications
Collection of publications in chronological order.
2026
- PVLDBiPDB: SQL with ML and LLM Predicates (Towards a Database Engine for AI)Udesh Kumarasinghe, Tyler Liu, Ahmed Mahmood, and 2 more authorsProceedings of the VLDB Endowment, 2026
Structured Query Language (SQL) has remained the standard query language for databases, and is highly optimized for processing structured data. However, it is inefficient for applications that leverage the capabilities of large language models (LLMs) to comprehend and extract semantic information from structured and unstructured data. This results in complex engineering and multiple data migration operations that transfer data between the data source and the LLM inference platform to couple them. We demonstrate iPDB, a system that supports in-database LLM inference using an extended declarative SQL syntax and new optimizations that result in efficient query processing of LLM-enabled SQL queries that outperform state-of-the-art systems.
@article{ipdb:vldb:2026, author = {Kumarasinghe, Udesh and Liu, Tyler and Mahmood, Ahmed and Liu, Chunwei and Aref, Walid G.}, title = {iPDB: SQL with ML and LLM Predicates (Towards a Database Engine for AI)}, year = {2026}, issn = {2150-8097}, publisher = {VLDB Endowment}, journal = {Proceedings of the VLDB Endowment}, volume = {19}, number = {12}, pages = {4782--4785}, numpages = {4}, url = {https://doi.org/10.14778/3827998.3828121}, doi = {10.14778/3827998.3828121}, keywords = {semantic query processing, in-database inference, large language models, query optimization}, series = {PVLDB '26}, } - arXiviPDB – Optimizing Semantic SQL QueriesUdesh Kumarasinghe, Tyler Liu, Ahmed R. Mahmood, and 2 more authorsJan 2026
The Structured Query Language (SQL) has remained the standard query language for databases. SQL is highly optimized for processing structured data laid out in relations. Meanwhile, in the present application development landscape, it is highly desirable to utilize the power of learned models to perform complex tasks. Large language models (LLMs) have been shown to understand and extract information from unstructured textual data. However, SQL as a query language and accompanying relational database systems are either incompatible or inefficient for workloads that require leveraging learned models. This results in complex engineering and multiple data migration operations that move data between the data sources and the model inference platform. This paper presents iPDB, a relational data system that supports in-database machine learning (ML) and large language model (LLM) inferencing using extended SQL syntax. In iPDB, LLMs and ML calls can function as semantic projects, as predicates to perform semantic selects and semantic joins, or for semantic grouping in group-by clauses. iPDB has a new relational predict operator along with semantic query optimizations that enable users to write and efficiently execute semantic SQL queries, outperforming other state-of-the-art systems by 2.5x mean speedup, with speedups of up to 30x.
@misc{ipdb:arxiv:2026,
  author = {Kumarasinghe, Udesh and Liu, Tyler and Mahmood, Ahmed R. and Liu, Chunwei and Aref, Walid G.},
  title = {iPDB -- Optimizing Semantic SQL Queries},
  year = {2026},
  month = jan,
  publisher = {arXiv},
  doi = {10.48550/ARXIV.2601.16432},
  url = {https://arxiv.org/abs/2601.16432},
  keywords = {Databases (cs.DB), Machine Learning (cs.LG), FOS: Computer and information sciences},
}
2024
-
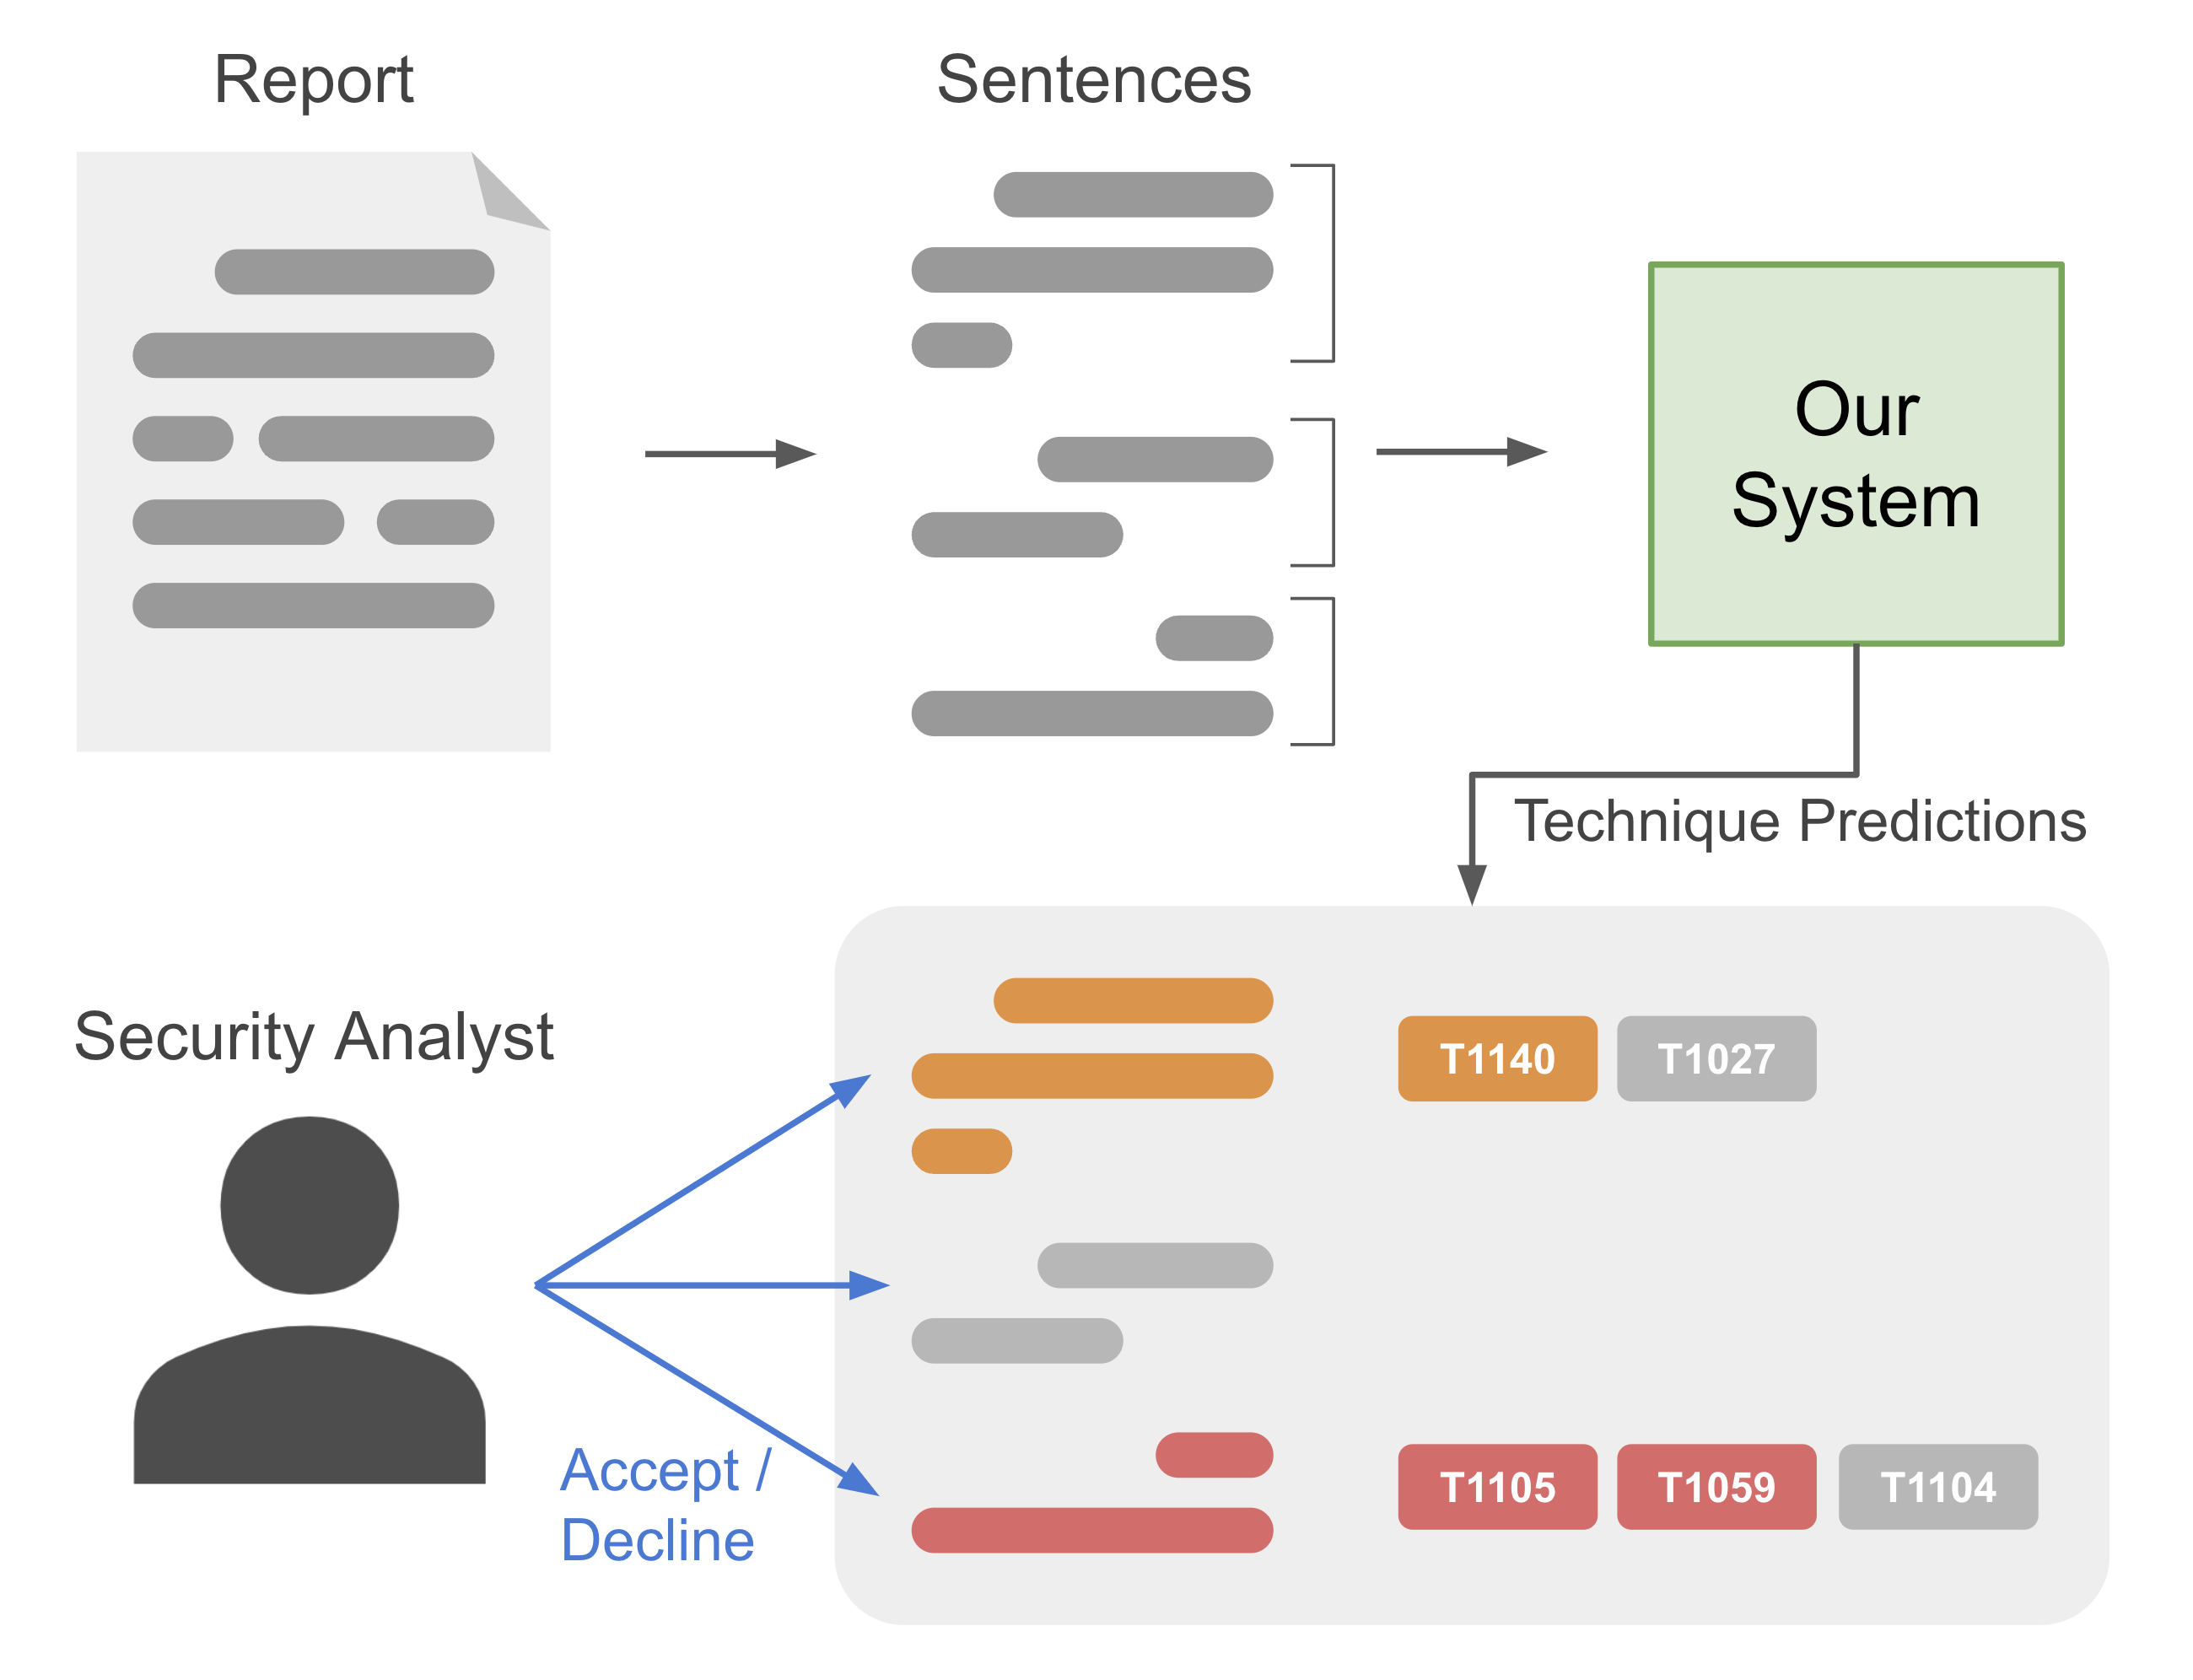 Semantic Ranking for Automated Adversarial Technique Annotation in Security TextUdesh Kumarasinghe, Ahmed Lekssays, Husrev Taha Sencar, and 3 more authorsIn Proceedings of the 19th ACM Asia Conference on Computer and Communications Security, Singapore, Singapore, 2024
We introduce a novel approach for mapping attack behaviors described in threat analysis reports to entries in an adversarial techniques knowledge base. Our method leverages a multi-stage ranking architecture to efficiently rank the most related techniques based on their semantic relevance to the input text. Each ranker in our pipeline uses a distinct design for text representation. To enhance relevance modeling, we leverage pretrained language models, which we fine-tune for the technique annotation task. While generic large language models are not yet capable of fully addressing this challenge, we obtain very promising results. We achieve a recall rate improvement of +35% compared to the previous state-of-the-art results. We further create new public benchmark datasets for training and validating methods in this domain, which we release to the research community aiming to promote future research in this important direction.
@inproceedings{sem_rank_threat:asiaccs:2024, author = {Kumarasinghe, Udesh and Lekssays, Ahmed and Sencar, Husrev Taha and Boughorbel, Sabri and Elvitigala, Charitha and Nakov, Preslav}, title = {Semantic Ranking for Automated Adversarial Technique Annotation in Security Text}, year = {2024}, isbn = {9798400704826}, publisher = {Association for Computing Machinery}, address = {New York, NY, USA}, url = {https://doi.org/10.1145/3634737.3645000}, doi = {10.1145/3634737.3645000}, booktitle = {Proceedings of the 19th ACM Asia Conference on Computer and Communications Security}, pages = {49–62}, numpages = {14}, keywords = {threat intelligence, TTP annotation, text ranking, text attribution}, location = {Singapore, Singapore}, series = {ASIA CCS '24}, } -
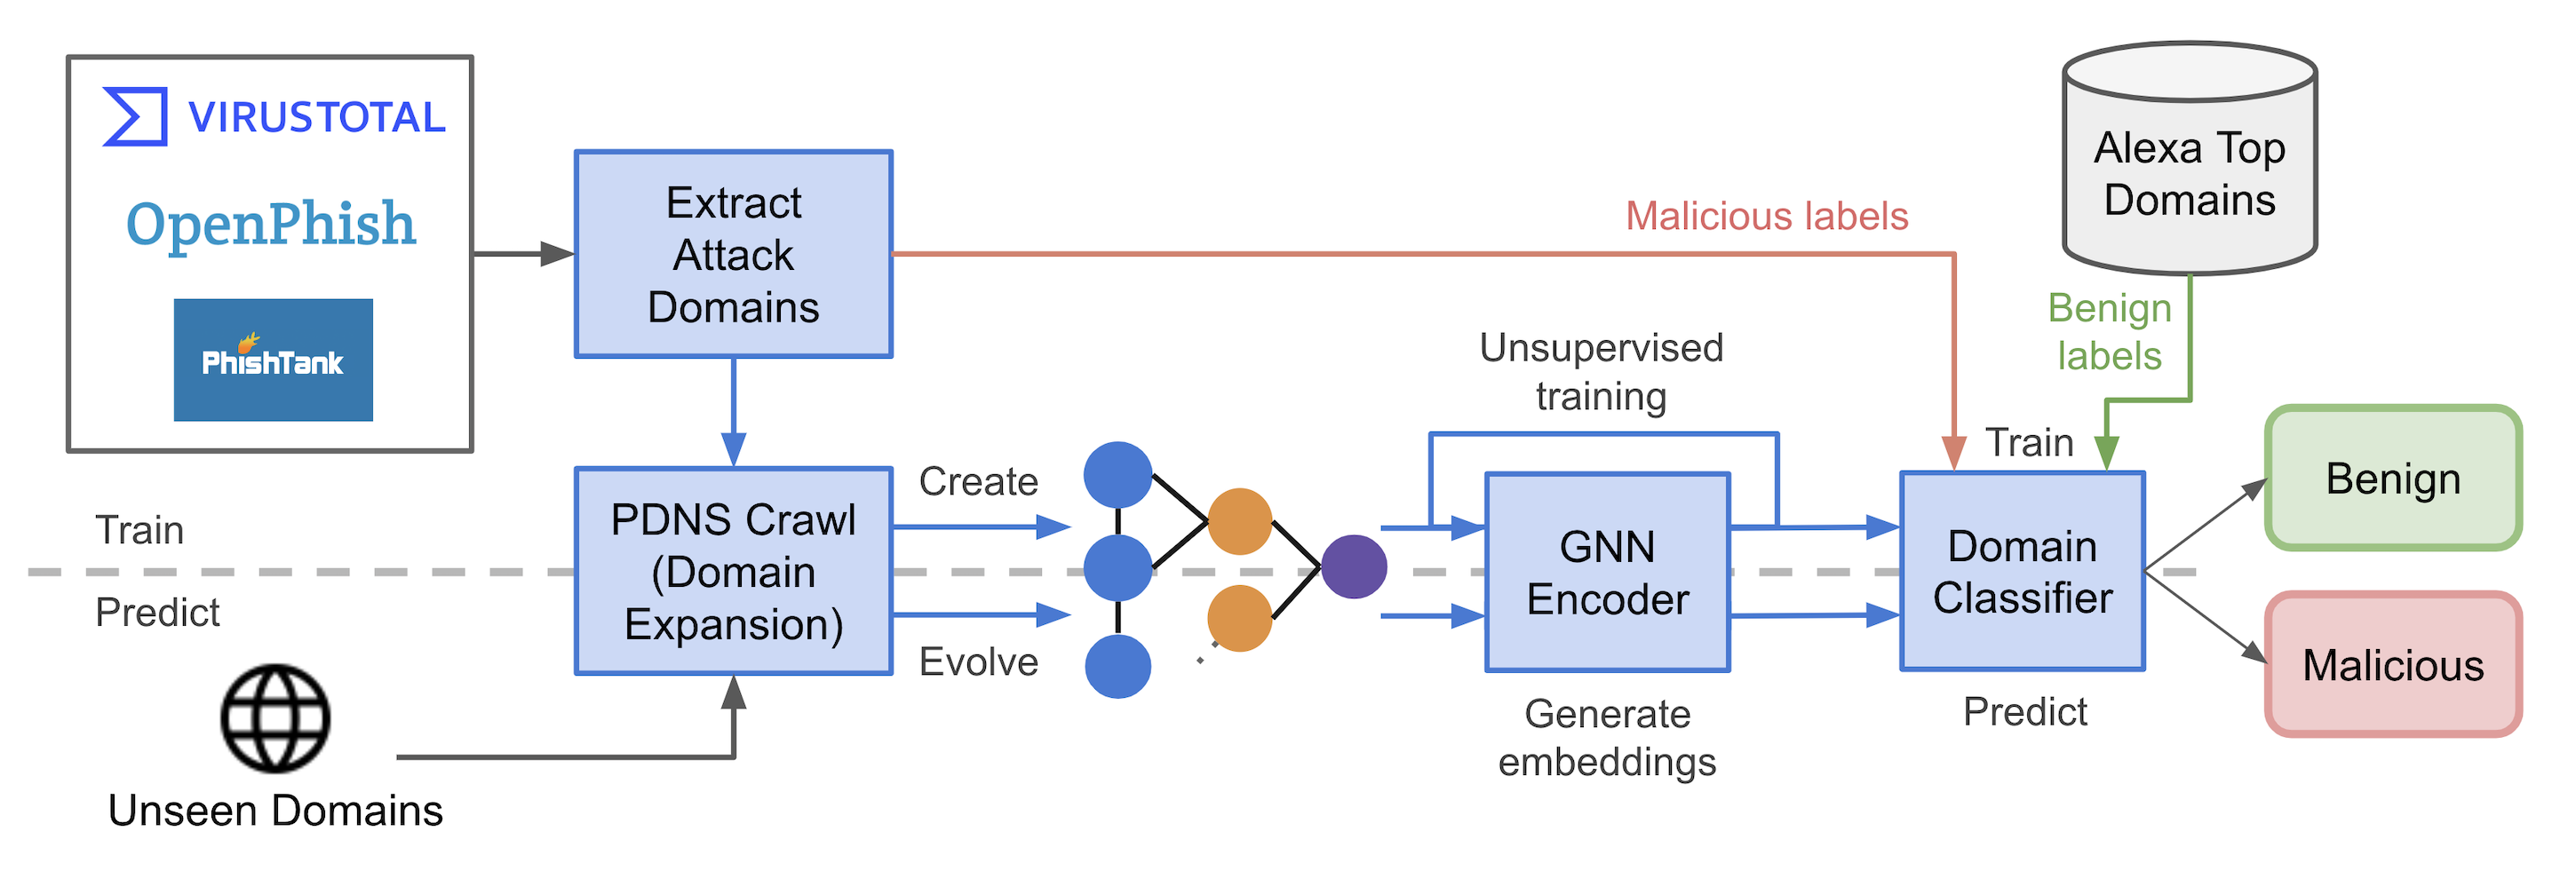 Blocklist-Forecast: Proactive Domain Blocklisting by Identifying Malicious Hosting InfrastructureUdesh Kumarasinghe, Mohamed Nabeel, and Charitha ElvitigalaIn Proceedings of the 27th International Symposium on Research in Attacks, Intrusions and Defenses, Padua, Italy, 2024
Domain blocklists play an important role in blocking malicious domains reaching users. However, existing blocklists are reactive in nature and slow to react to attacks, by which time the damage is already caused. This is mainly due to the fact that existing blocklists and reputation systems rely on either website content or user interactions with the websites in order to ascertain if a website is malicious. In this work, we explore the possibility of predicting malicious domains proactively, given a seed list of malicious domains from such reactive blocklists. We observe that malicious domains often share the infrastructure utilized for previous attacks, reuse or rotate resources. Leveraging this observation, we selectively crawl passive DNS data to identify domains in the "neighborhood" of seed malicious domains extracted from reactive blocklists. Due to the increased utilization of cloud hosting, not all such domains in the neighborhood are malicious. Further vetting is required to identify unseen malicious domains. Along with the proximity, we identify that hosting and lexical features help distinguish malicious domains from benign ones. We model the infrastructure as a heterogeneous network graph and design a graph neural network to detect malicious domains. Our approach is blocklist-agnostic in that it can work with any blocklist and detect new malicious domains. We demonstrate our approach utilizing 7 month longitudinal data from three popular blocklists, PhishTank, OpenPhish, and VirusTotal. Our experimental results show that, our approach for VirusTotal feed detects 4.7 unseen malicious domains for every seed malicious domain at a very low FPR of 0.059. Further, we observe the concerning trend that 47% of predicted malicious domains that are later flagged in VirusTotal are identified only after more than 3 weeks to months since our model detects them.
@inproceedings{blocklist_forecast:raid:2024,
  author = {Kumarasinghe, Udesh and Nabeel, Mohamed and Elvitigala, Charitha},
  title = {Blocklist-Forecast: Proactive Domain Blocklisting by Identifying Malicious Hosting Infrastructure},
  year = {2024},
  isbn = {9798400709593},
  publisher = {Association for Computing Machinery},
  address = {New York, NY, USA},
  url = {https://doi.org/10.1145/3678890.3678925},
  doi = {10.1145/3678890.3678925},
  booktitle = {Proceedings of the 27th International Symposium on Research in Attacks, Intrusions and Defenses},
  pages = {35–48},
  numpages = {14},
  keywords = {domain association, graph learning, malicious domains, passive DNS},
  location = {Padua, Italy},
  series = {RAID '24},
}
2023
-
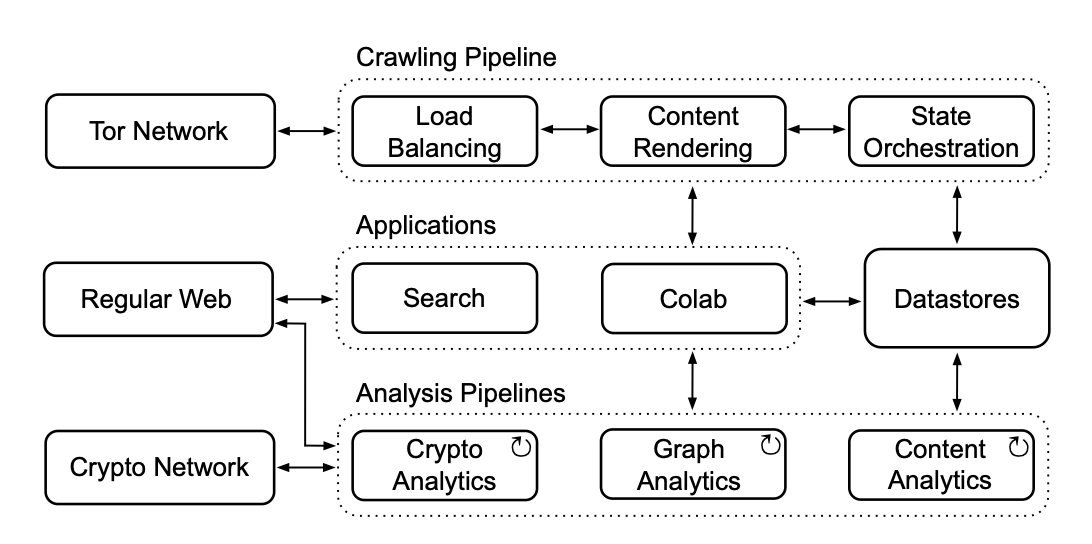 Dizzy: Large-Scale Crawling and Analysis of Onion ServicesYazan Boshmaf, Isuranga Perera, Udesh Kumarasinghe, and 2 more authorsIn Proceedings of the 18th International Conference on Availability, Reliability and Security, Benevento, Italy, 2023
With nearly 2.5m users, onion services have become the prominent part of the darkweb. Over the last five years alone, the number of onion domains has increased 20x, reaching more than 700k unique domains in January 2022. As onion services host various types of illicit content, they have become a valuable resource for darkweb research and an integral part of e-crime investigation and threat intelligence. However, this content is largely un-indexed by today’s search engines and researchers have to rely on outdated or manually-collected datasets that are limited in scale, scope, or both. To tackle this problem, we built Dizzy: An open-source crawling and analysis system for onion services. Dizzy implements novel techniques to explore, update, check, and classify onion services at scale, without overwhelming the Tor network. We deployed Dizzy in April 2021 and used it to analyze more than 63.3m crawled onion webpages, focusing on domain operations, web content, cryptocurrency usage, and web graph. Our main findings show that onion services are unreliable due to their high churn rate, have a relatively small number of reachable domains that are often similar and illicit, enjoy a growing underground cryptocurrency economy, and have a graph that is relatively tightly-knit to, but topologically different from, the regular web’s graph.
@inproceedings{10.1145/3600160.3600167,
  author = {Boshmaf, Yazan and Perera, Isuranga and Kumarasinghe, Udesh and Liyanage, Sajitha and Al Jawaheri, Husam},
  title = {Dizzy: Large-Scale Crawling and Analysis of Onion Services},
  year = {2023},
  isbn = {9798400707728},
  publisher = {Association for Computing Machinery},
  address = {New York, NY, USA},
  url = {https://doi.org/10.1145/3600160.3600167},
  doi = {10.1145/3600160.3600167},
  booktitle = {Proceedings of the 18th International Conference on Availability, Reliability and Security},
  articleno = {9},
  numpages = {11},
  location = {Benevento, Italy},
  series = {ARES '23}
}
2022
-
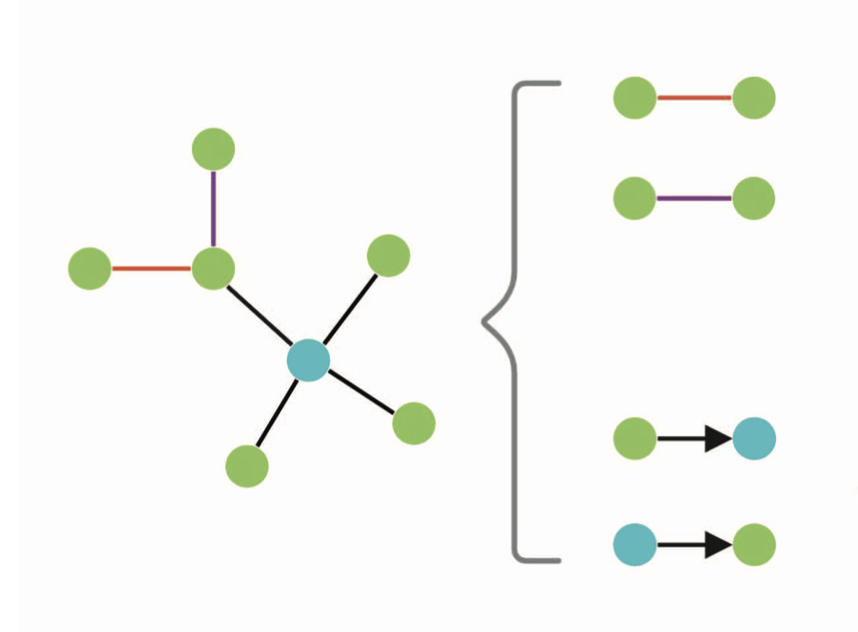 HeteroGuard: Defending Heterogeneous Graph Neural Networks against Adversarial AttacksU. Kumarasinghe, M. Nabeel, K. De Zoysa, and 2 more authorsIn 2022 IEEE International Conference on Data Mining Workshops (ICDMW), Dec 2022
Graph neural networks (GNNs) have achieved re-markable success in many application domains including drug discovery, program analysis, social networks, and cyber security. However, it has been shown that they are not robust against adversarial attacks. In the recent past, many adversarial attacks against homogeneous GNNs and defenses have been proposed. However, most of these attacks and defenses are ineffective on heterogeneous graphs as these algorithms optimize under the assumption that all edge and node types are of the same and further they introduce semantically incorrect edges to perturbed graphs. Here, we first develop, HetePR-BCD, a training time (i.e. poisoning) adversarial attack on heterogeneous graphs that outperforms the start of the art attacks proposed in the literature. Our experimental results on three benchmark heterogeneous graphs show that our attack, with a small perturbation budget of 15 %, degrades the performance up to 32 % (Fl score) compared to existing ones. It is concerning to mention that existing defenses are not robust against our attack. These defenses primarily modify the GNN's neural message passing operators assuming that adversarial attacks tend to connect nodes with dissimilar features, but this assumption does not hold in heterogeneous graphs. We construct HeteroGuard, an effective defense against training time attacks including HetePR-BCD on heterogeneous models. HeteroGuard outperforms the existing defenses by 3–8 % on Fl score depending on the benchmark dataset.
@inproceedings{heteroguard:icdmw:2022, author = {Kumarasinghe, U. and Nabeel, M. and Zoysa, K. De and Gunawardana, K. and Elvitigala, C.}, booktitle = {2022 IEEE International Conference on Data Mining Workshops (ICDMW)}, title = {HeteroGuard: Defending Heterogeneous Graph Neural Networks against Adversarial Attacks}, year = {2022}, volume = {}, issn = {}, pages = {698-705}, doi = {10.1109/ICDMW58026.2022.00096}, keywords = {graph neural networks;adversarial attacks;defenses;heterogeneous graphs}, url = {https://ieeexplore.ieee.org/abstract/document/10031190}, publisher = {IEEE Computer Society}, address = {Los Alamitos, CA, USA}, month = dec, } -
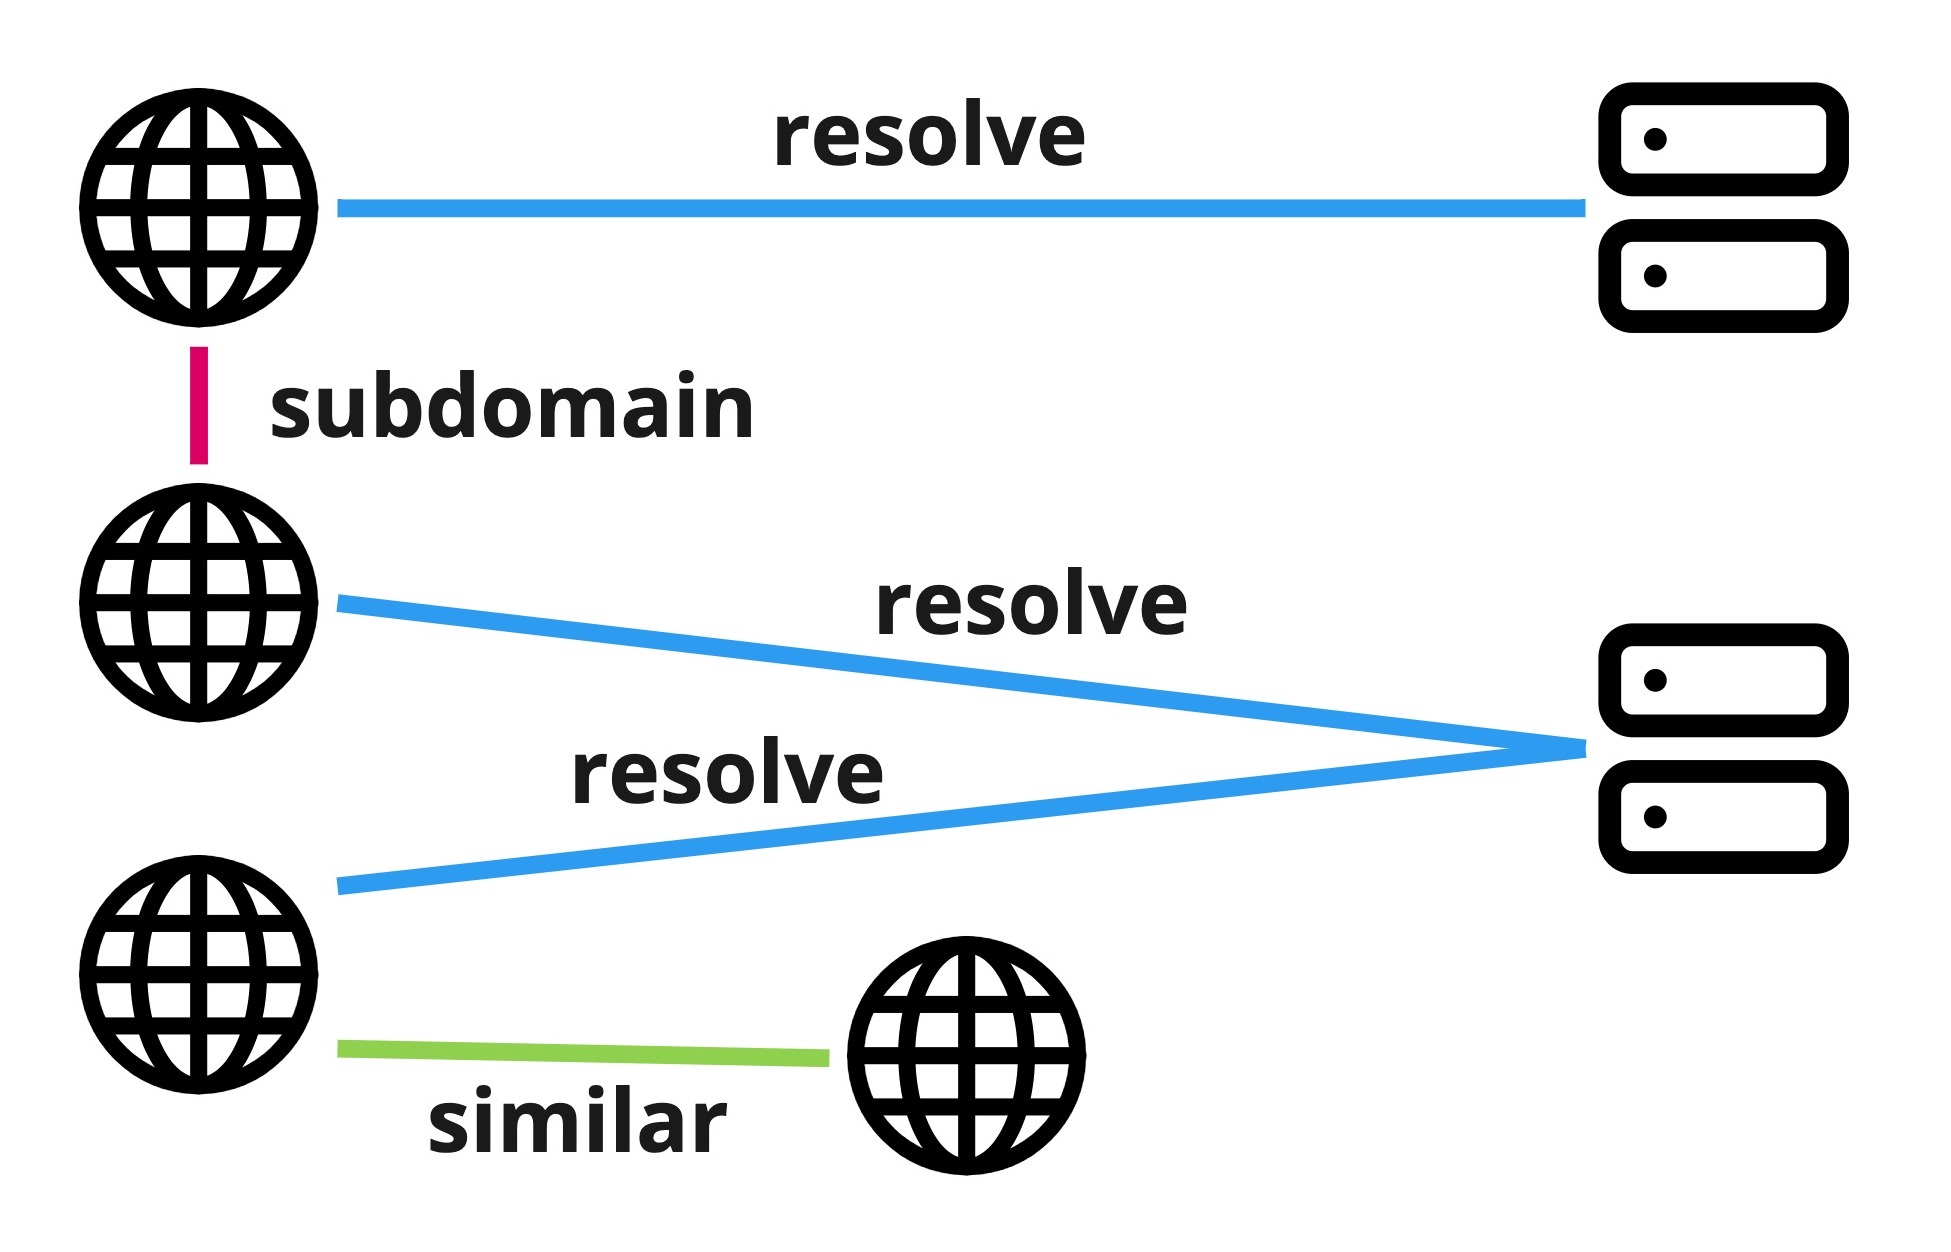 PDNS-Net: A Large Heterogeneous Graph Benchmark Dataset of Network Resolutions for Graph LearningUdesh Kumarasinghe, Fatih Deniz, and Mohamed NabeelMar 2022
In order to advance the state of the art in graph learning algorithms, it is necessary to construct large real-world datasets. While there are many benchmark datasets for homogeneous graphs, only a few of them are available for heterogeneous graphs. Furthermore, the latter graphs are small in size rendering them insufficient to understand how graph learning algorithms perform in terms of classification metrics and computational resource utilization. We introduce, PDNS-Net, the largest public heterogeneous graph dataset containing 447K nodes and 897K edges for the malicious domain classification task. Compared to the popular heterogeneous datasets IMDB and DBLP, PDNS-Net is 38 and 17 times bigger respectively. We provide a detailed analysis of PDNS-Net including the data collection methodology, heterogeneous graph construction, descriptive statistics and preliminary graph classification performance. The dataset is publicly available at this https URL. Our preliminary evaluation of both popular homogeneous and heterogeneous graph neural networks on PDNS-Net reveals that further research is required to improve the performance of these models on large heterogeneous graphs.
@misc{pdns_net:arxiv:2022,
  doi = {10.48550/ARXIV.2203.07969},
  url = {https://arxiv.org/abs/2203.07969},
  author = {Kumarasinghe, Udesh and Deniz, Fatih and Nabeel, Mohamed},
  keywords = {Machine Learning (cs.LG), Cryptography and Security (cs.CR), FOS: Computer and information sciences, FOS: Computer and information sciences},
  title = {PDNS-Net: A Large Heterogeneous Graph Benchmark Dataset of Network Resolutions for Graph Learning},
  publisher = {arXiv},
  year = {2022},
  month = mar,
  copyright = {Creative Commons Attribution 4.0 International},
}